
Extraction benchmarks
In order to optimize your extraction settings, you need to know how accurately your current extraction settings perform when applied to a set of documents. You can test your extraction settings against a set of documents by running an extraction benchmark.
Ideally, this document set should contain documents whose classification and extraction results are always correct, and these ideal documents are referred to as golden files. Running an extraction benchmark processes these golden files using the project extraction settings and compares the extraction results against the stored golden file values. Selecting a field column in the Summary table loads all documents with that field into the Selection document set.
There are three different extraction benchmark scenarios you can generate. Each open in the Extraction Benchmark window:
- Benchmark - Extraction Selected Class icon Extraction Benchmark (Selected Class):
-
 When this setting is selected, extraction using your current
extraction settings for the selected class is run against the selected
document set in the Documents window. The extraction
results are compared to the results in the golden files. Since no
classification is run for this setting, if one or more of the documents in
the test document are not of the selected class, their extraction results
are blank in the Extraction Benchmark window.
- Extraction Benchmark (Selected Class And Children):
-
 When this setting is selected,
classification and then extraction using your current extraction settings
for the selected class and child classes is run against the selected
document set in the Documents window. If a document
is not classified as the selected class or one of its child classes, it is
not included in the Summary or
Details table in the Extraction
Benchmark window.
- Extraction Benchmark (All Classes):
-
 When this setting is selected,
classification and then extraction using your current extraction settings
for the project is run against the selected document set in the
Documents window. The results are displayed in
the Summary and Details table
on the Extraction Benchmark window.
Once a value is extracted when the benchmark is processed, the comparison between the extracted value and the stored value can result in the following:
- Correct valid fields:
-
This result occurs if the currently extracted field value and the stored value are equal. It is not displayed to the user in Validation as it has a valid field status and does not require manual validation. Fields with this status are highlighted in green.
This was formerly known as the OK result.
- Correct invalid fields:
-
This result occurs if the currently extracted value and the stored value are equal but the field status is invalid. For example, a failed validation rule caused the result to be invalid, or the minimum confidence extraction threshold was not met. A field with this result in a production batch needs to be manually validated by a user. Fields with this status are highlighted in blue.
This result was formerly part of the Reject result.
- Incorrect invalid fields:
-
This result occurs because the currently extracted value and the stored value are not equal and the field status is invalid. For example, a field has no extraction result but there is a stored result, or the extracted result differs from the stored result in some other way. A field with this result in a production batch needs to be manually validated by a user. Fields with this status are highlighted in yellow.
This result was formerly part of the Reject result.
- Incorrect valid fields:
-
This result occurs if the currently extracted value and the stored value are not equal but the field status is valid. This result is known as a false positive because it is mistakenly marked valid. It is not displayed to the user in Validation as it has a valid field status and does not require manual validation. Fields with this status are highlighted in red. Any results with this status need to be addressed before the project is put into production so invalid data is not overlooked.
This result was formerly known as the Error result.
Regardless of the type of extraction benchmark performed, the settings displayed on this window are the same.
You can see how many of the selected document set are processed by the progress bar at the bottom of the screen. When the processing is complete, the total number of documents and any skipped documents are displayed.
- Legend:
-
This group shows the four possible results. Each is given a unique label and color so they are readily recognizable in the Summary and Details results.
-
Correct valid fields
-
Correct invalid fields
-
Incorrect invalid fields
-
Incorrect valid fields
-
- Summary:
-
This group provides overall results for the extraction benchmark. It looks at all of the extracted field and provides details about the following:
-
The total percentage of fields from all documents for each of four results. This is the "All Fields" column.
-
The percentage of each of the four results for each extracted field. Each extracted field has its own column in this table.
The sum of each column in this table should equal 100%, and the goal of your extraction settings is to have the highest percentage in the first row. This represents the correct results that match the desired values.
You can sort the individual rows in ascending or descending order by selecting the relevant result letter (A, B, C, or D). To revert to the default sort order, select Revert to Default Sort Order.
If you select a field in this table, the Selection document set displays only the documents that contain the corresponding field and extraction result. For example, you want to see only the documents that have the Invoice Number field incorrectly extracted as valid. Since this is an undesired result, you can focus on that subset of documents and update your extraction settings for that field. When you are finished with the Invoice Number field, you can move on to other fields that have undesirable extraction results.
-
- Details:
-
This group provides more detailed information about each document and field. Each row is a single document. The name, class, percentages of A, B, C, and D, and the results for each extracted field are displayed.
The Class column is not displayed when extraction is run for the selected class only.
The first five or six columns are fixed, so if there is a long list of fields, you can scroll the fields without losing sight of the file, class if applicable, and the cumulative extraction statistics.
Each individual field cell contains the results of the extraction benchmark. The six possible results are:
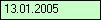
- Correct valid field (green with single value):
-
The extracted value for this field matches the desired value.
The following example shows a date field that has the correct value:
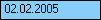
- Correct invalid field (blue with single value):
-
The extracted value for this field matches the desired value, but for some reason it is marked invalid.
The following example shows a date field that has the correct value, but was marked invalid because it did not meet the minimum confidence threshold.
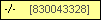
- Incorrect invalid field (yellow with conflicting values):
-
The extracted value for this field does not match the desired result and is marked invalid.
The following example shows an invoice number field that has the incorrect value. Because the extracted value and the desired value do not match, it is marked invalid. The desired value is displayed in brackets, and since there was no extracted value, it is empty.
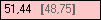
- Incorrect valid field (red with two values):
-
The extracted value does not match the desired value, yet the field is marked valid.
In situations like this, the field is not displayed during production, so it is important to eliminate these results by modifying the extraction settings before the project is used in production.
The following example shows a subtotal field that has an incorrect value, even though the extracted value and the desired value do not match.
- Field not in class (no highlighting or values):
-
A blank cell in the details table means that a field is not present in the class.
The following example shows an empty cell in the InvoiceDate column. The field is empty because the document in the corresponding row is classified as a different class that does not contain the InvoiceDate field.

- Field not found on document (no highlighting and missing values):
-
A blank cell that contains -/- means the field is present in the corresponding class but cannot be found on the document.
The following example shows a cell with no highlighting that contains a blank value. The field has a blank value (-/-) because the document was classified as an Invoice, yet there is no invoice number on the document.
If you want to view the file associated with an individual cell in this table, you can select a cell to select the document in the Documents window. You can also double-click the cell and open the Document Viewer for the corresponding document. All extracted field data is highlighted on the image.
By default, the documents listed in the Details table are listed in the order they are processed. If you want to rearrange the sort order, you can choose between the following values:
-
Select one of the summary headers (A, B, C, or D) to sort the results in ascending or descending order.
-
Select a field column header to sort the field results in ascending or descending alphabetical order.

-